
September 21, 2026
Enchant v3: Molecular superintelligence for end-to-end drug R&D
Fred Manby
PhD, Co-Founder and CTO
Matt Welborn
PhD, SVP, Machine Learning
Today, Iambic unveils Enchant v3, the next generation of our multimodal transformer model for drug discovery and the core AI technology powering Iambic’s molecular superintelligence platform. Enchant v3 is an architectural leap over Enchant v2, allowing us to test many drug-discovery hypotheses in parallel from early discovery through clinical development. We use Enchant to navigate key design decisions across our pipeline, predicting properties across target compound profiles.
The brain behind molecular superintelligence
Iambic’s mission is to make better technology for better medicines. We are advancing a molecular superintelligence platform designed to disrupt legacy drug discovery paradigms. Instead of treating each stage of drug discovery as a distinct technological challenge, we have designed a unified platform to address the totality of drug discovery and development– from hit identification to multiparameter lead optimization to clinical developability.
Molecular superintelligence emerges through the interplay between Enchant, guiding design and prioritization of experiments, with automated laboratory data generation to validate hypotheses and iteratively refine models. This engine for new medicines allows us to make hundreds of novel compounds per week, and test them in a diverse array of physicochemical, biological, and metabolic assays. With Enchant, we can make predictions across a wide array of preclinical and clinical endpoints.
Enchant was built for end-to-end drug R&D and works to:
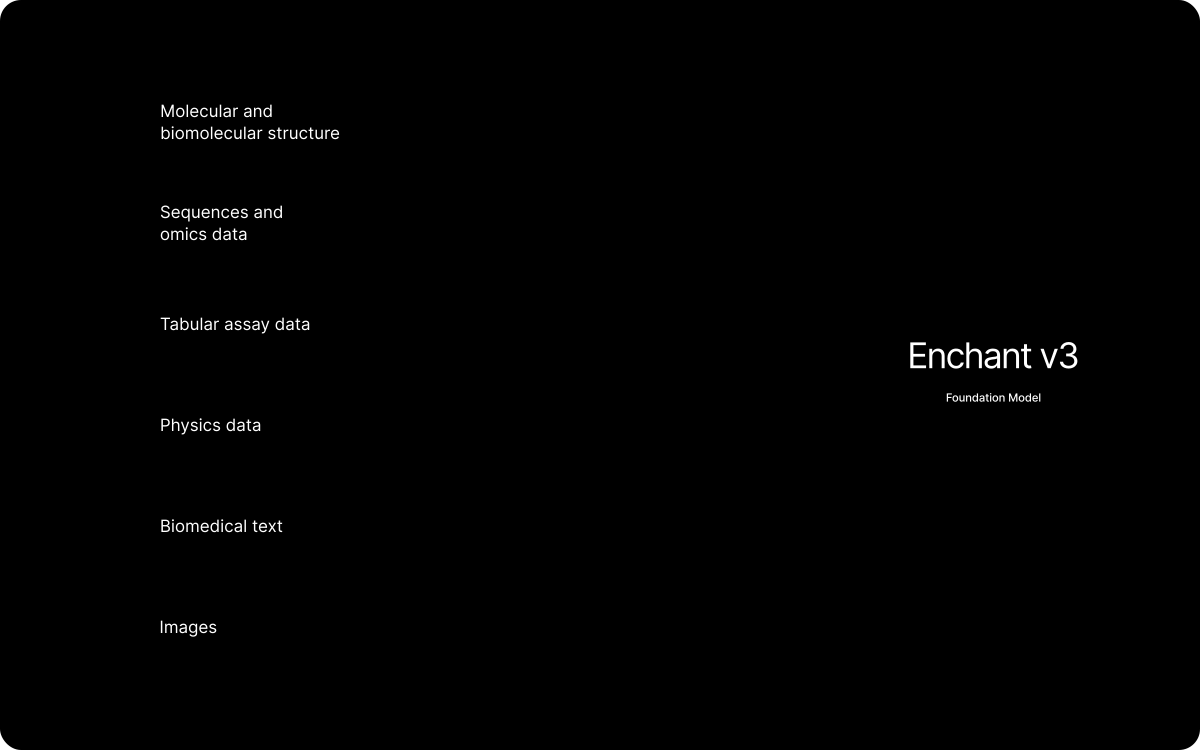
- Ingest diverse data: In drug discovery, we naturally encounter heterogeneous data, and so building a multimodal model was always a must. Enchant was built to ingest heterogeneous inputs, including molecular and biomolecular structures, sequence and omics data, tabular assay data, physics data, biomedical text, and images (Figure 1), to produce predictions across diverse preclinical and clinical endpoints. As new laboratory data are produced, Enchant continuously learns from them, enabling the platform to optimize toward differentiated drug candidates.
- Leverage model scale: Chemical and biological training data for any modality is often limited; multimodality allows Enchant to reach larger model scale by learning jointly across a wide range of data types and endpoints. As model scale is increased, Enchant gets better at predicting one endpoint by being trained on data from other related endpoints and on other molecules.
- Break through data walls: Enchant's ability to transfer learning between different endpoints means we can predict ‘expensive’ endpoints from ‘cheaper’ ones, in vivo properties from in vitro data, and clinical properties from preclinical studies.
- Convert model outputs into probability-guided decisions: Every Enchant prediction relies on uncertainty quantification to maximize useful information from laboratory experiments and prioritize potential compounds.
Enchant has allowed us to explore AI-enabled improvements over the legacy drug discovery paradigm and advance our wholly owned and differentiated drug pipeline. Read on for concrete examples.
How Enchant impacts discovery at Iambic
At Iambic, we are passionate about building incredible technologies and making those technologies advance potential medicines to and through the clinic. In service to this effort, Enchant was designed to operate at a significant scale, where we conduct model fine-tuning each week on hundreds of distinct molecular properties and make approximately 12 million inferences per month across our wholly owned and partnered drug discovery programs.
Enchant is used to predict endpoints for any target compound profile being considered for every discovery program. Uncertainty quantification tells us what experiments to run. Figure 2 illustrates a systematic view of compounds associated with a program, where compounds are ranked according to Enchant inferences, experimental measurements, and overall design score.
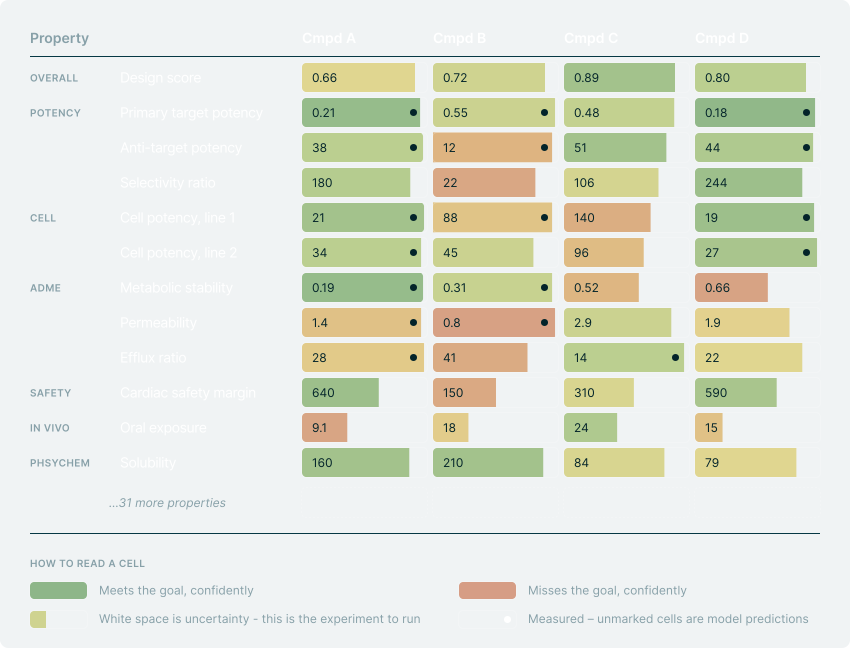
known about each compound, and the degree to which it conforms to a target compound profile.
Enchant plays a critical role in our discovery programs. Two examples that demonstrate how better technology can lead to better medicines are IAM-C1 (our dual inhibitor of CDK2/4) and IAM217 (our allosteric KIF18A inhibitor).
Example #1: IAM-C1 for CDK2/4
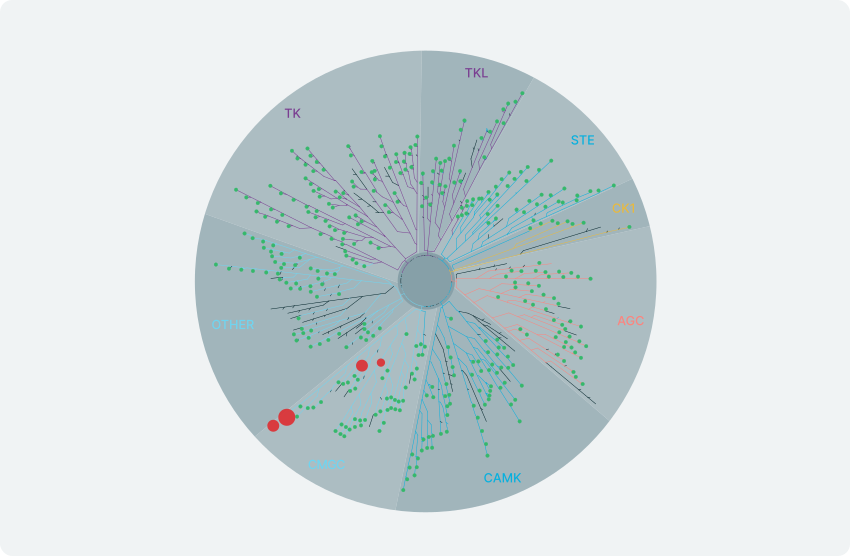
IAM-C1 is a selective dual inhibitor of CDK2 and CDK4, two cell-cycle kinases that are frequently dysregulated in various cancers. IAM-C1 addresses one of the hardest problems in kinase drug discovery: intentionally designing highly selective polypharmacology. For a molecule to potently inhibit CDK2 and CDK4, it must block both a key cancer-driving pathway and a major resistance mechanism while sparing other members of the CDK family. This design choice is critical as inhibition of closely related kinases, such as CDK6, as well as essential CDKs including CDK1, CDK7, and CDK9, can substantially narrow the therapeutic window. Achieving this precise profile is exceptionally challenging because the ATP-binding pockets across the CDK family are highly conserved.
Using Enchant and high-throughput synthesis and biological assays, we directly optimized for this hard-to-drug profile. Enchant was leveraged both to optimize the profile and to prioritize the experiments anticipated to improve model fidelity in the most important predictive regime. This optimization process took place in parallel with the panoply of other considerations required to arrive at our clinical candidate, IAM-C1.
Example #2: IAM217 for KIF18A
IAM217 is a differentiated KIF18A allosteric inhibitor being studied for triple-negative breast cancer, ovarian cancer, and other solid tumor indications. KIF18A is a mitotic motor protein on which chromosomally unstable tumors (including the therapeutic indications mentioned) can become selectively dependent. Although its inhibition may disrupt tumor-cell division while sparing healthy dividing cells, creating a clinically differentiated KIF18A inhibitor is a demanding, multiparameter challenge – potency and durable target engagement must be combined with strong pharmacokinetics, low drug-to-drug interaction risk, convenient dosing, and sufficient brain penetration to address intracranial disease.
We used Enchant throughout the design-make-test-analyze cycle to simultaneously optimize properties and engineer IAM217. In preclinical studies, IAM217 produced approximately 90 percent regression of established intracranial tumors while a presumed clinical-stage comparator produced no regression. IAM217 also achieved comparable tumor-growth inhibition at substantially lower total and unbound plasma exposures than the standard of care and demonstrated a clean drug-to-drug interaction profile with pharmacokinetics, supporting once-daily oral dosing.
Beyond IAM-C1 and IAM217, we see Enchant enabling work across our drug discovery programs. Enchant was designed not only to increase our execution speed but also to improve the probability of success for translating potential therapeutics to and through the clinic. Ultimately, final proof comes in the form of human clinical data – both IAM-C1 and IAM217 are advancing toward IND application submission.
Enchant v3: Achieving scalable predictability
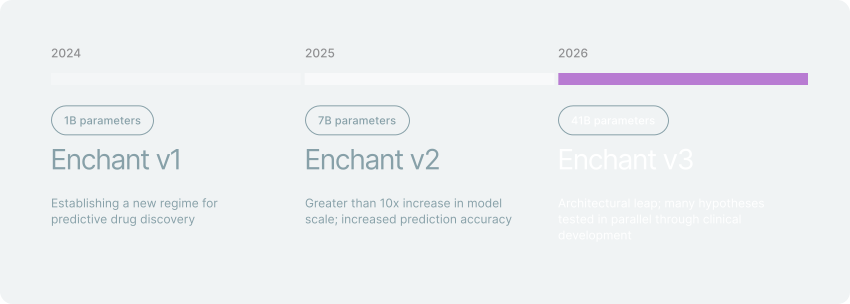
In 2024, we trained Enchant v1 with 1 billion parameters. In 2025, we trained Enchant v2 with 7 billion parameters.
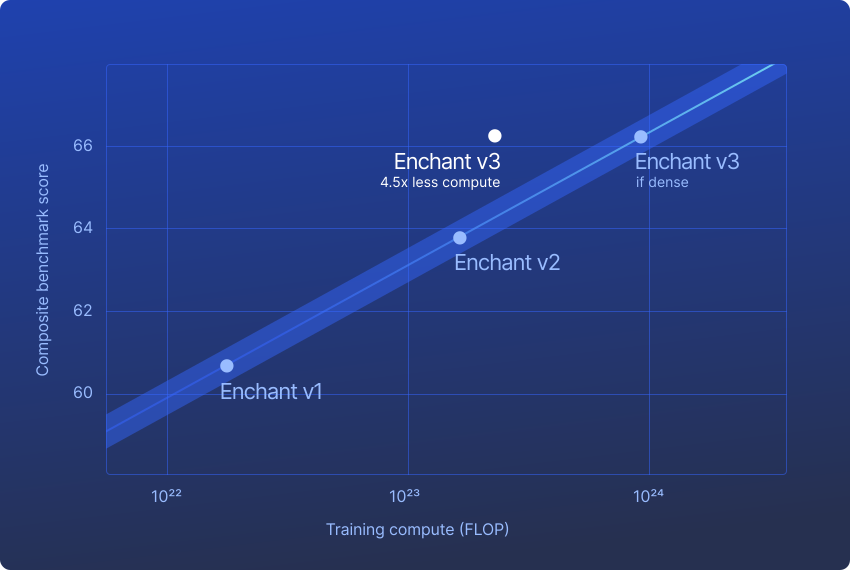
Today, we unveil Enchant v3 – a 41-billion parameter model that leverages an increased data scale, a broader range of data modalities, and a mixture-of-experts architecture to achieve even greater accuracy, as highlighted by Figure 4.
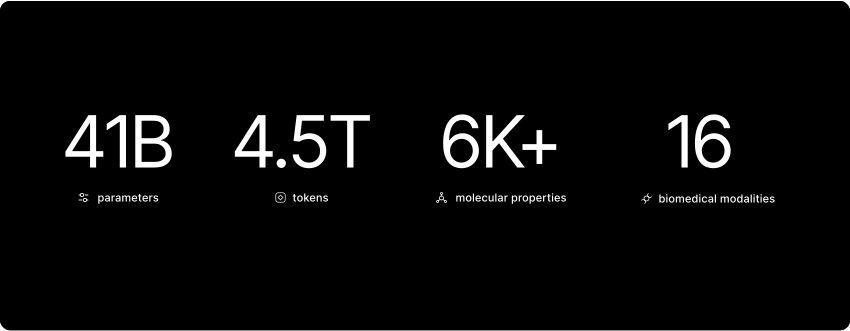
New capabilities of Enchant v3 include inverse design, omics-based prediction, image-based prediction, and peptides – which have risen in popularity for discovery following the success of GLP-1s.
Across three generations of Enchant, we have found that increased scale leads to improved prediction accuracy across a diverse range of preclinical and clinical endpoints. As shown in Figure 5, with Enchant, we are not only building a model to make transformational and translational drug predictions – we are investing in innovative technology that can give Iambic a differentiated edge when executing drug discovery and development efforts for itself and its partners.
Enchant was designed to enable two critical objectives:
- Increase probability of success: Every new drug program benefits from unified intelligence, the ability to test many hypotheses at once and more accurately predict preclinical and clinical endpoints. We built Enchant to nominate lead compounds with the hope of increasing the probability of success to translate that compound to and through clinical trials.
- Expand therapeutic opportunity: Although our wholly owned clinical pipeline and partner pipeline have oncology, neuroscience, and inflammation & immunology programs, we do not feel limited to these therapeutic areas or even the small molecule therapeutic modality. Enchant enables us to leverage proprietary, partnered, and public data to build a holistic approach designed to predict preclinical and clinical properties for a range of targets, therapeutic areas, and potentially new therapeutic modalities.
Enchant has made significant progress in a relatively short time, as shown in Figure 6:
Enchant excels at token-based structure prediction
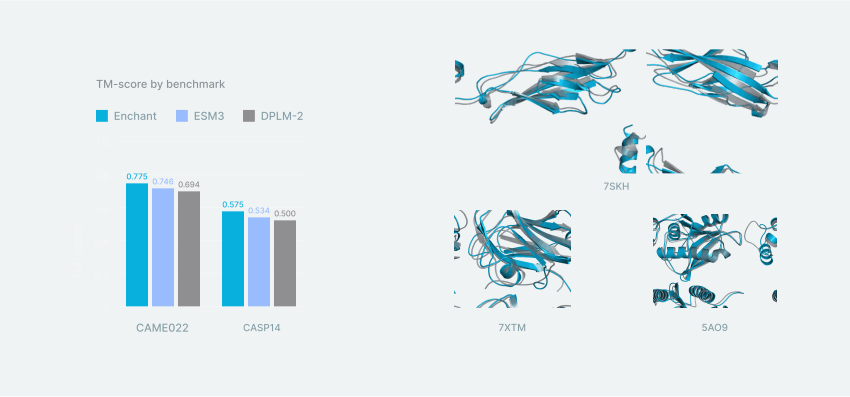
Biomolecular structures are one of the many modalities we use to train Enchant, and we include them because model predictions of assays that involve specific proteins are enhanced by the addition of extra information about proteins. Given our NeuralPLexer technology’s ability to make structure-based predictions, we have not been specifically focused on such capabilities for Enchant. As shown in Figure 7, Enchant has acquired the capacity to make predictions of folded protein structure, where on held out structures in the CASP14 and CAMEO22 sets, Enchant’s predictions surpass other token-based methods like ESM3 and DPLM-2 in quality.
Enchant drives an engine for new medicines
We are excited to deploy Enchant v3 to our internal and partner drug discovery work to address the totality of the drug discovery and development process. Furthermore, we anticipate continuing to explore the capacity of Enchant v3 to answer broader types of research questions based on the myriad modalities that the model is aware of.
Enchant learns from experimental data, sharpening its predictions with each cycle from platform to bench and back. Because Enchant was built to navigate vast chemical and biological space and sparse data regimes, we believe it could improve the probability of success at every stage of drug discovery and development.
With Enchant, we aim to systematically expand the boundaries of what is druggable and redefine how novel medicines are made to address unmet patient needs. Moreover, we believe that we can operate an engine for designing, optimizing, and developing new medicines – repeatedly, with conviction, and at scale.
More to come.